
陳寬宸
陳文正
孫偉芳
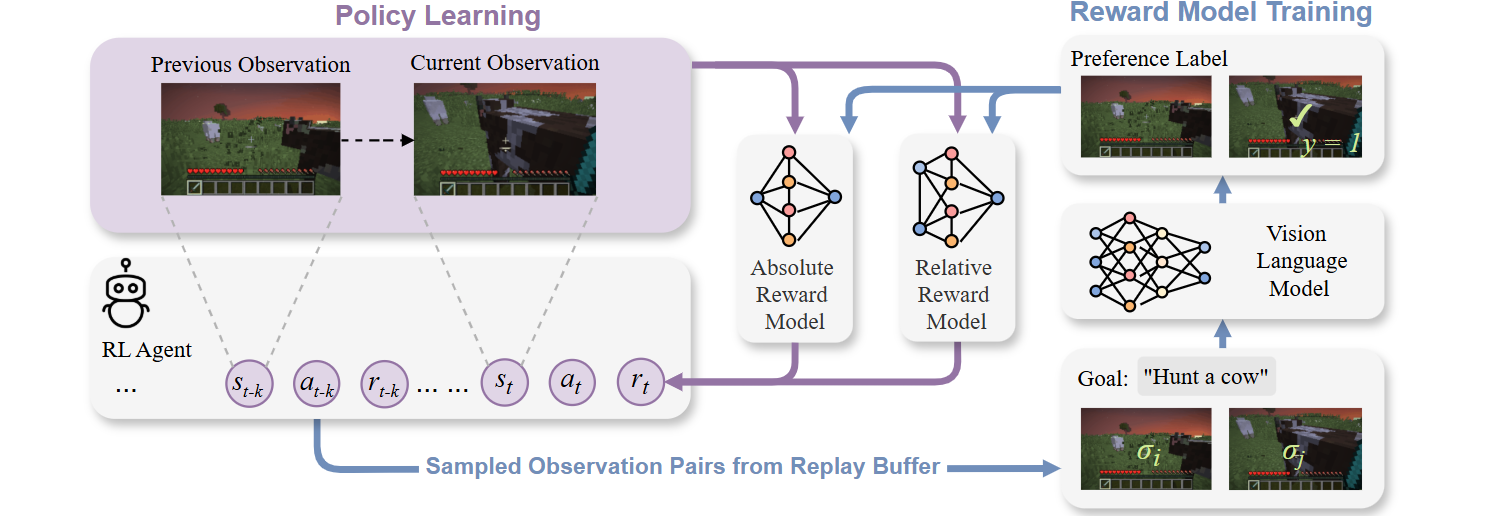
The long-term vision of artificial intelligence is to develop autonomous agents capable of continually improving through self-directed learning. A key obstacle toward this goal is the reliance of reinforcement learning (RL) on manually designed reward functions, which are often difficult to construct for open-ended tasks with abstract objectives. To address this challenge, we present VLM-AR3L, a framework that leverages Vision-Language Models (VLMs) to provide both absolute and relative rewards for RL without explicit human reward engineering. VLM-AR3L interprets an agent’s visual observations in the context of a natural language task goal, and learns both absolute and relative rewards from VLM-generated preference labels. The absolute reward model predicts scalar evaluations for individual states, while the relative reward model compares consecutive observations to infer progress or regression toward the task goal. Their integration combines the stability of state-based evaluation with the robustness of comparative supervision. We evaluate VLM-AR3L across benchmarks spanning classic control, manipulation, and open-world embodied tasks, with a particular focus on Minecraft given its visual complexity and long-horizon decision-making requirements. Experimental results show that VLM-AR3L consistently outperforms prior VLM-based reward learning methods.
@misc{chen2026vlmar3lvisionlanguagemodelsabsolute,
      title={VLM-AR3L: Vision-Language Models for Absolute and Relative Rewards in Reinforcement Learning},
      author={Kuan-Chen Chen and Winston Chen and Wei-Fang Sun and Min-Chun Hu},
      year={2026},
      eprint={2607.00483},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2607.00483},
}
 MIS Lab